Technical
Multi-GPU in ComfyUI: What Distributed, MultiGPU and NetDist Actually Do
· RenderBob team
"Just use multi-GPU" is common advice for ComfyUI capacity problems, and it hides a lot of confusion, because the popular extensions labelled multi-GPU solve three different problems.
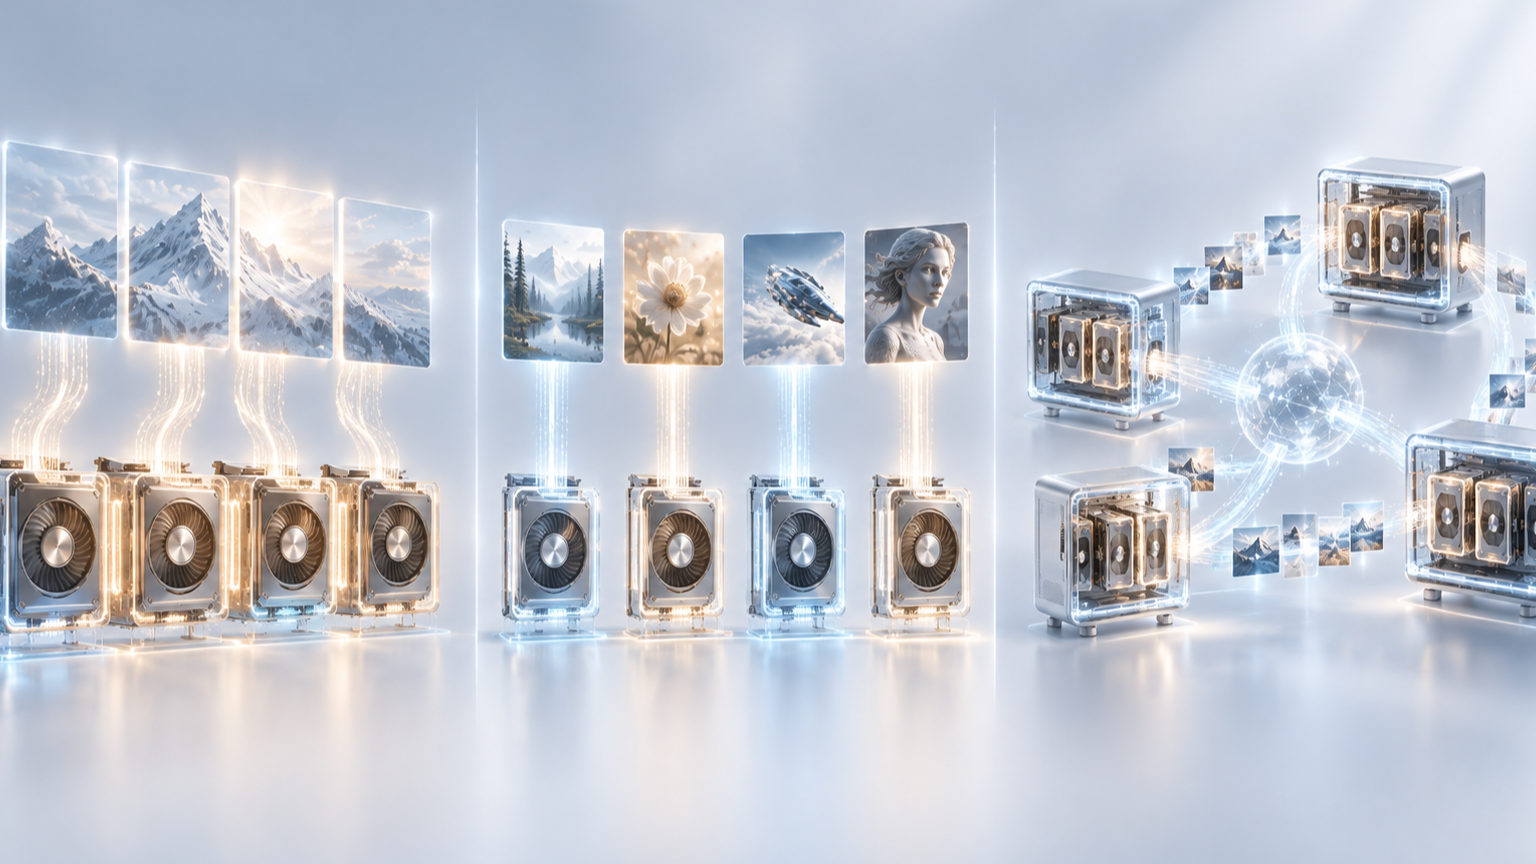
"Just use multi-GPU" is common advice for ComfyUI capacity problems, and it hides a lot of confusion, because the popular extensions labelled multi-GPU solve three different problems. Picking the wrong one for your bottleneck wastes hardware. Here is the map.
Batch parallelism: ComfyUI-Distributed
This fans independent work across multiple GPUs and machines: each worker runs the same workflow with, say, a different seed, and the master collects the results. It is ideal when you want more outputs or faster batch upscaling and you have several GPUs (local or cloud) to throw at it. It does not combine the VRAM of multiple GPUs. Each worker still has to fit the job on its own card, and static distribution can leave a slow GPU as a straggler holding up the batch. Great for throughput; useless for a single job that does not fit on one card.
Memory splitting: ComfyUI-MultiGPU / DisTorch
This spreads a single model's components (including GGUF/GGML layers) across multiple GPUs, or offloads them to CPU, so a workflow that exceeds one card's VRAM can still run. This is the tool for the my-model-doesn't-fit problem. It enhances memory management, not parallelism. The workflow steps still execute sequentially, just with pieces loaded across devices. It buys you capacity, not speed.
Cross-machine execution: ComfyUI_NetDist and friends
This runs workflows across networked machines, passing intermediate data (latents saved as files) between instances. It is the older, more manual approach to spreading work across separate PCs, and it comes with the data-locality tax: each instance needs the checkpoints and VAEs it will use.
What none of them do
None gives you a true, VRAM-pooling, automatically-scheduling render farm out of the box. Batch parallelism does not help a single oversized job. Memory splitting does not make anything faster. Cross-machine tools do not schedule intelligently or pool memory. And none of them reason about a mixed fleet (fast discrete cards, a roomy unified-memory box, and metered cloud workers) deciding which job belongs where.
These extensions are useful building blocks, and for a specific bottleneck the right one is a real fix. Stitching them into a pipeline that routes each job to the right hardware, keeps the environment reproducible across all of it, and holds cost and security rules (batch here, memory-split there, burst to cloud when it overflows) is a control-plane job the building blocks do not do for you. Know which problem you actually have, reach for the extension that solves that one, and recognise that one system over the whole fleet is a different and larger thing than any single multi-GPU node.
More from the blog
- Human Authorship Is Becoming the Unit of Value
The Oscars' 2026 AI rules, Cannes' unpublished competition stance, a patchwork of festival policies, and the Thaler copyright denial all ask how much of a film a human authored.
- Ideation Is the Green Zone: Where Studios Allow AI and Where They Stop
Netflix's generative AI guidance for production partners treats concept work as the open case and final deliverables as the restricted one. That split is spreading as a working template.