Case study
Case Study: One Control Plane Across Five Providers
· RenderBob team
A composite case study: a studio running owned GPUs, two clouds and two API model providers behind a single governed control plane.
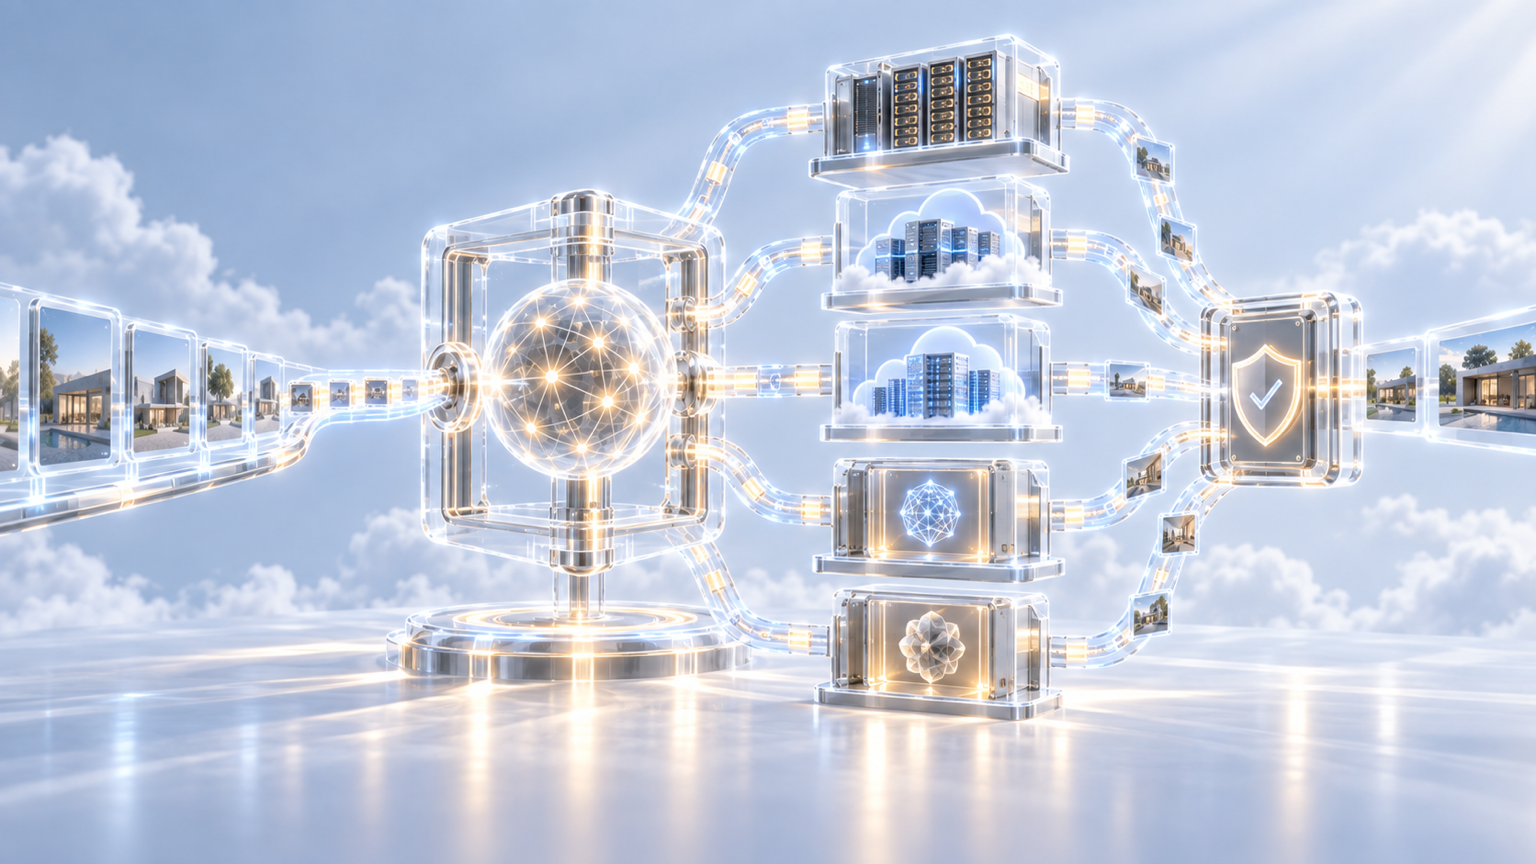
Illustrative composite of common multi-provider studio patterns, not a named client.
A mid-size studio ended up, almost by accident, running five kinds of compute at once: owned GPU workstations, a unified-memory box, a cloud provider for burst rendering, and two API model providers for specific frontier passes. Each had arrived to solve a real problem. Together, ungoverned, they had become a mess: five bills, five sets of credentials, no consistent view of cost, and no single answer to "which client's work ran where."
The problems were the predictable ones. Cost was opaque: three metered sources plus owned hardware, with no unified cost-per-frame, so nobody could say which jobs were cheap where. Governance was thin: artists reached for whichever provider was handy, including for an NDA client whose material was never supposed to leave owned hardware. Reproducibility slipped: a workflow that ran on an owned node behaved differently when someone pushed it to a cloud worker with a drifted environment. And provider outages or deprecations hit without a failover plan.
The fix was not to cut providers. Each was useful. It was to put one control plane over all of them. Artists submitted to a single layer. Routing became policy: iteration on owned nodes, overflow to cloud, specific passes to the right API model, and NDA-tagged jobs restricted to owned hardware, never any external provider. Every destination, owned, cloud, or API, ran the same pinned environment or was reached through a consistent interface, so results were reproducible across all of them. Cost per frame was reported across the whole mix in one place, with caps and idle shutdown on the metered sources. And because models sat behind an abstraction, swapping or failing over a provider was a configuration change.
Five providers stopped being five separate risks and became one governed fleet. The owner could finally answer what a render cost, where a client's data went, and what would happen if a provider had an outage, questions that had no clean answer when each provider was its own island. In 2026, a serious studio will be multi-provider. The model zoo, the hardware shortage and the local/cloud split guarantee it. The choice is whether to govern them as one system or suffer them as many.
More from the blog
- Critterz and the Retired Model: A Feature-Length Lesson in Tool Dependency
Critterz was pitched as an AI-assisted animated feature in about nine months for around $30 million. Its Cannes story is what happens when the video model in the pipeline is shut down.
- Wan 2.2 on a 6GB Card: A Real Low-VRAM Case Study
A community Wan 2.2 14B workflow generates a second of video on an RTX 3050 6GB in under five minutes. Here is the stacked technique set that makes that possible.